- Full-attention mechanism with O(L^2) time and memory complexity.
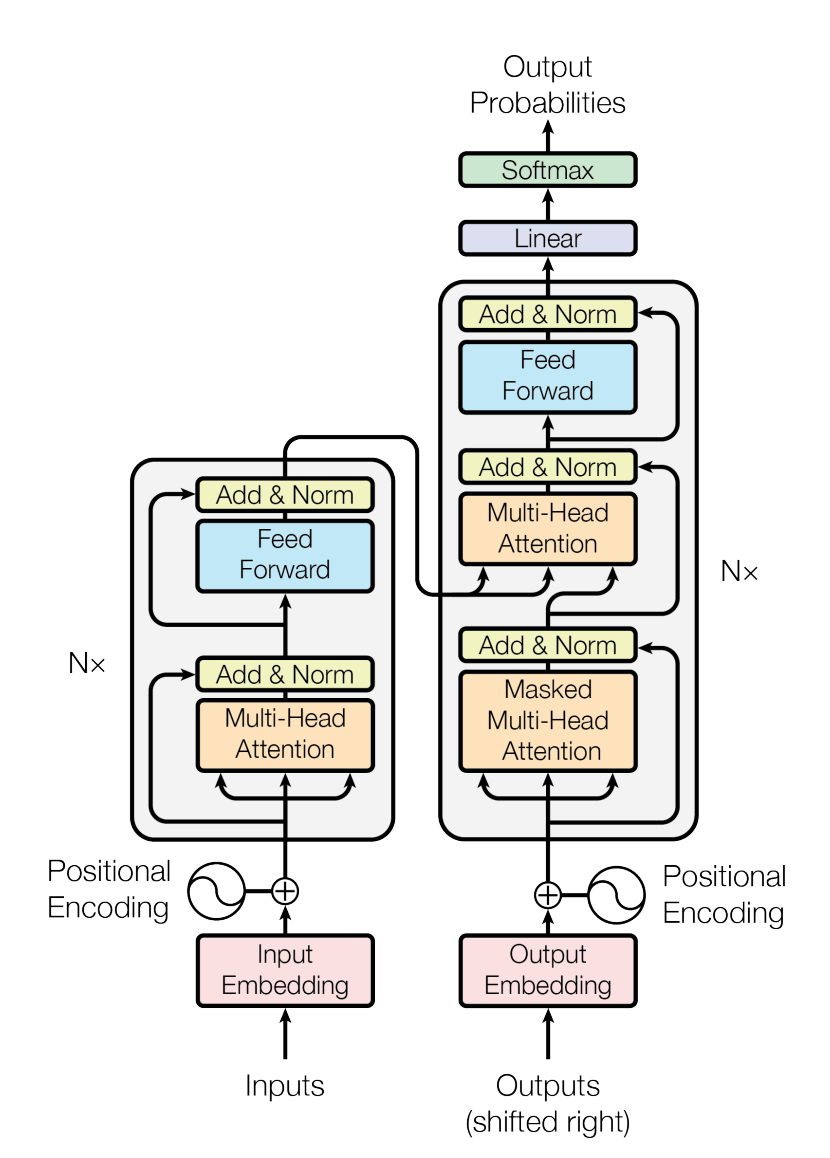
- Classic encoder-decoder proposed by Vaswani et al. (2017) with a multi-head attention mechanism.
- An MLP multi-step decoder that predicts long time-series sequences in a single forward operation rather than step-by-step.
- It employs encoded autoregressive features obtained from a convolution network.
- It uses window-relative positional embeddings derived from harmonic functions.
- Absolute positional embeddings obtained from calendar features are utilized.
Vanilla Transformer
VanillaTransformer
BaseModel
VanillaTransformer
Vanilla Transformer, following implementation of the Informer paper, used as baseline.
The architecture has three distinctive features:
- Full-attention mechanism with O(L^2) time and memory complexity.
- An MLP multi-step decoder that predicts long time-series sequences in a single forward operation rather than step-by-step.
- It employs encoded autoregressive features obtained from a convolution network.
- It uses window-relative positional embeddings derived from harmonic functions.
- Absolute positional embeddings obtained from calendar features are utilized.
VanillaTransformer.fit
fit method, optimizes the neural network’s weights using the
initialization parameters (learning_rate, windows_batch_size, …)
and the loss function as defined during the initialization.
Within fit we use a PyTorch Lightning Trainer that
inherits the initialization’s self.trainer_kwargs, to customize
its inputs, see PL’s trainer arguments.
The method is designed to be compatible with SKLearn-like classes
and in particular to be compatible with the StatsForecast library.
By default the model is not saving training checkpoints to protect
disk memory, to get them change enable_checkpointing=True in __init__.
Parameters:
Returns:
VanillaTransformer.predict
Trainer execution of predict_step.
Parameters:
Returns: